How Regal Reduced AI Agent Latency by 26%

Why Latency Matters

On a phone call, your brand has less than a second to make a good first impression. If an AI agent hesitates before its opening response, callers notice, and many hang up. That pause can feel awkward, undermining trust in the brand, and directly affects whether the conversation continues.

This is what makes voice AI fundamentally different from other ways people interact with language models today. When you're using ChatGPT or any chat-based assistant, a slightly slow first response is a minor annoyance, even an expectation. On a phone call, the stakes are higher because callers are accustomed to hearing a human on the other side of the line.

Contact center operators track call abandonment rates closely for exactly this reason: the first few seconds of a call determine whether the rest of it happens. That pause before an AI agent speaks is one of the most detectable signals that you're not talking to a human. In a cascaded voice AI architecture (where a separate LLM and text-to-speech provider each take their turn), that pause has a specific name: time to first token (TTFT).

TTFT is how long it takes the language model to begin generating a response after the caller finishes speaking. It's the biggest driver of perceived latency in a voice AI system. And over the past several weeks, it's where we've been focusing our engineering work.

The result: end-to-end response latency had a 26% improvement in roughly three weeks. This blog will cover what goes on behind each AI agent call, and the experiments we ran to improve latency.

The Problem With Processing the Same Instructions Over and Over

Every time your AI agent responds, it sends a request to the LLM. That request includes the full system prompt: all the instructions about how the agent should behave, what tools it has access to, and how to handle different scenarios. On a long call, that prompt gets submitted and re-processed on every single turn.

Here’s a look at what happens behind every AI agent call:
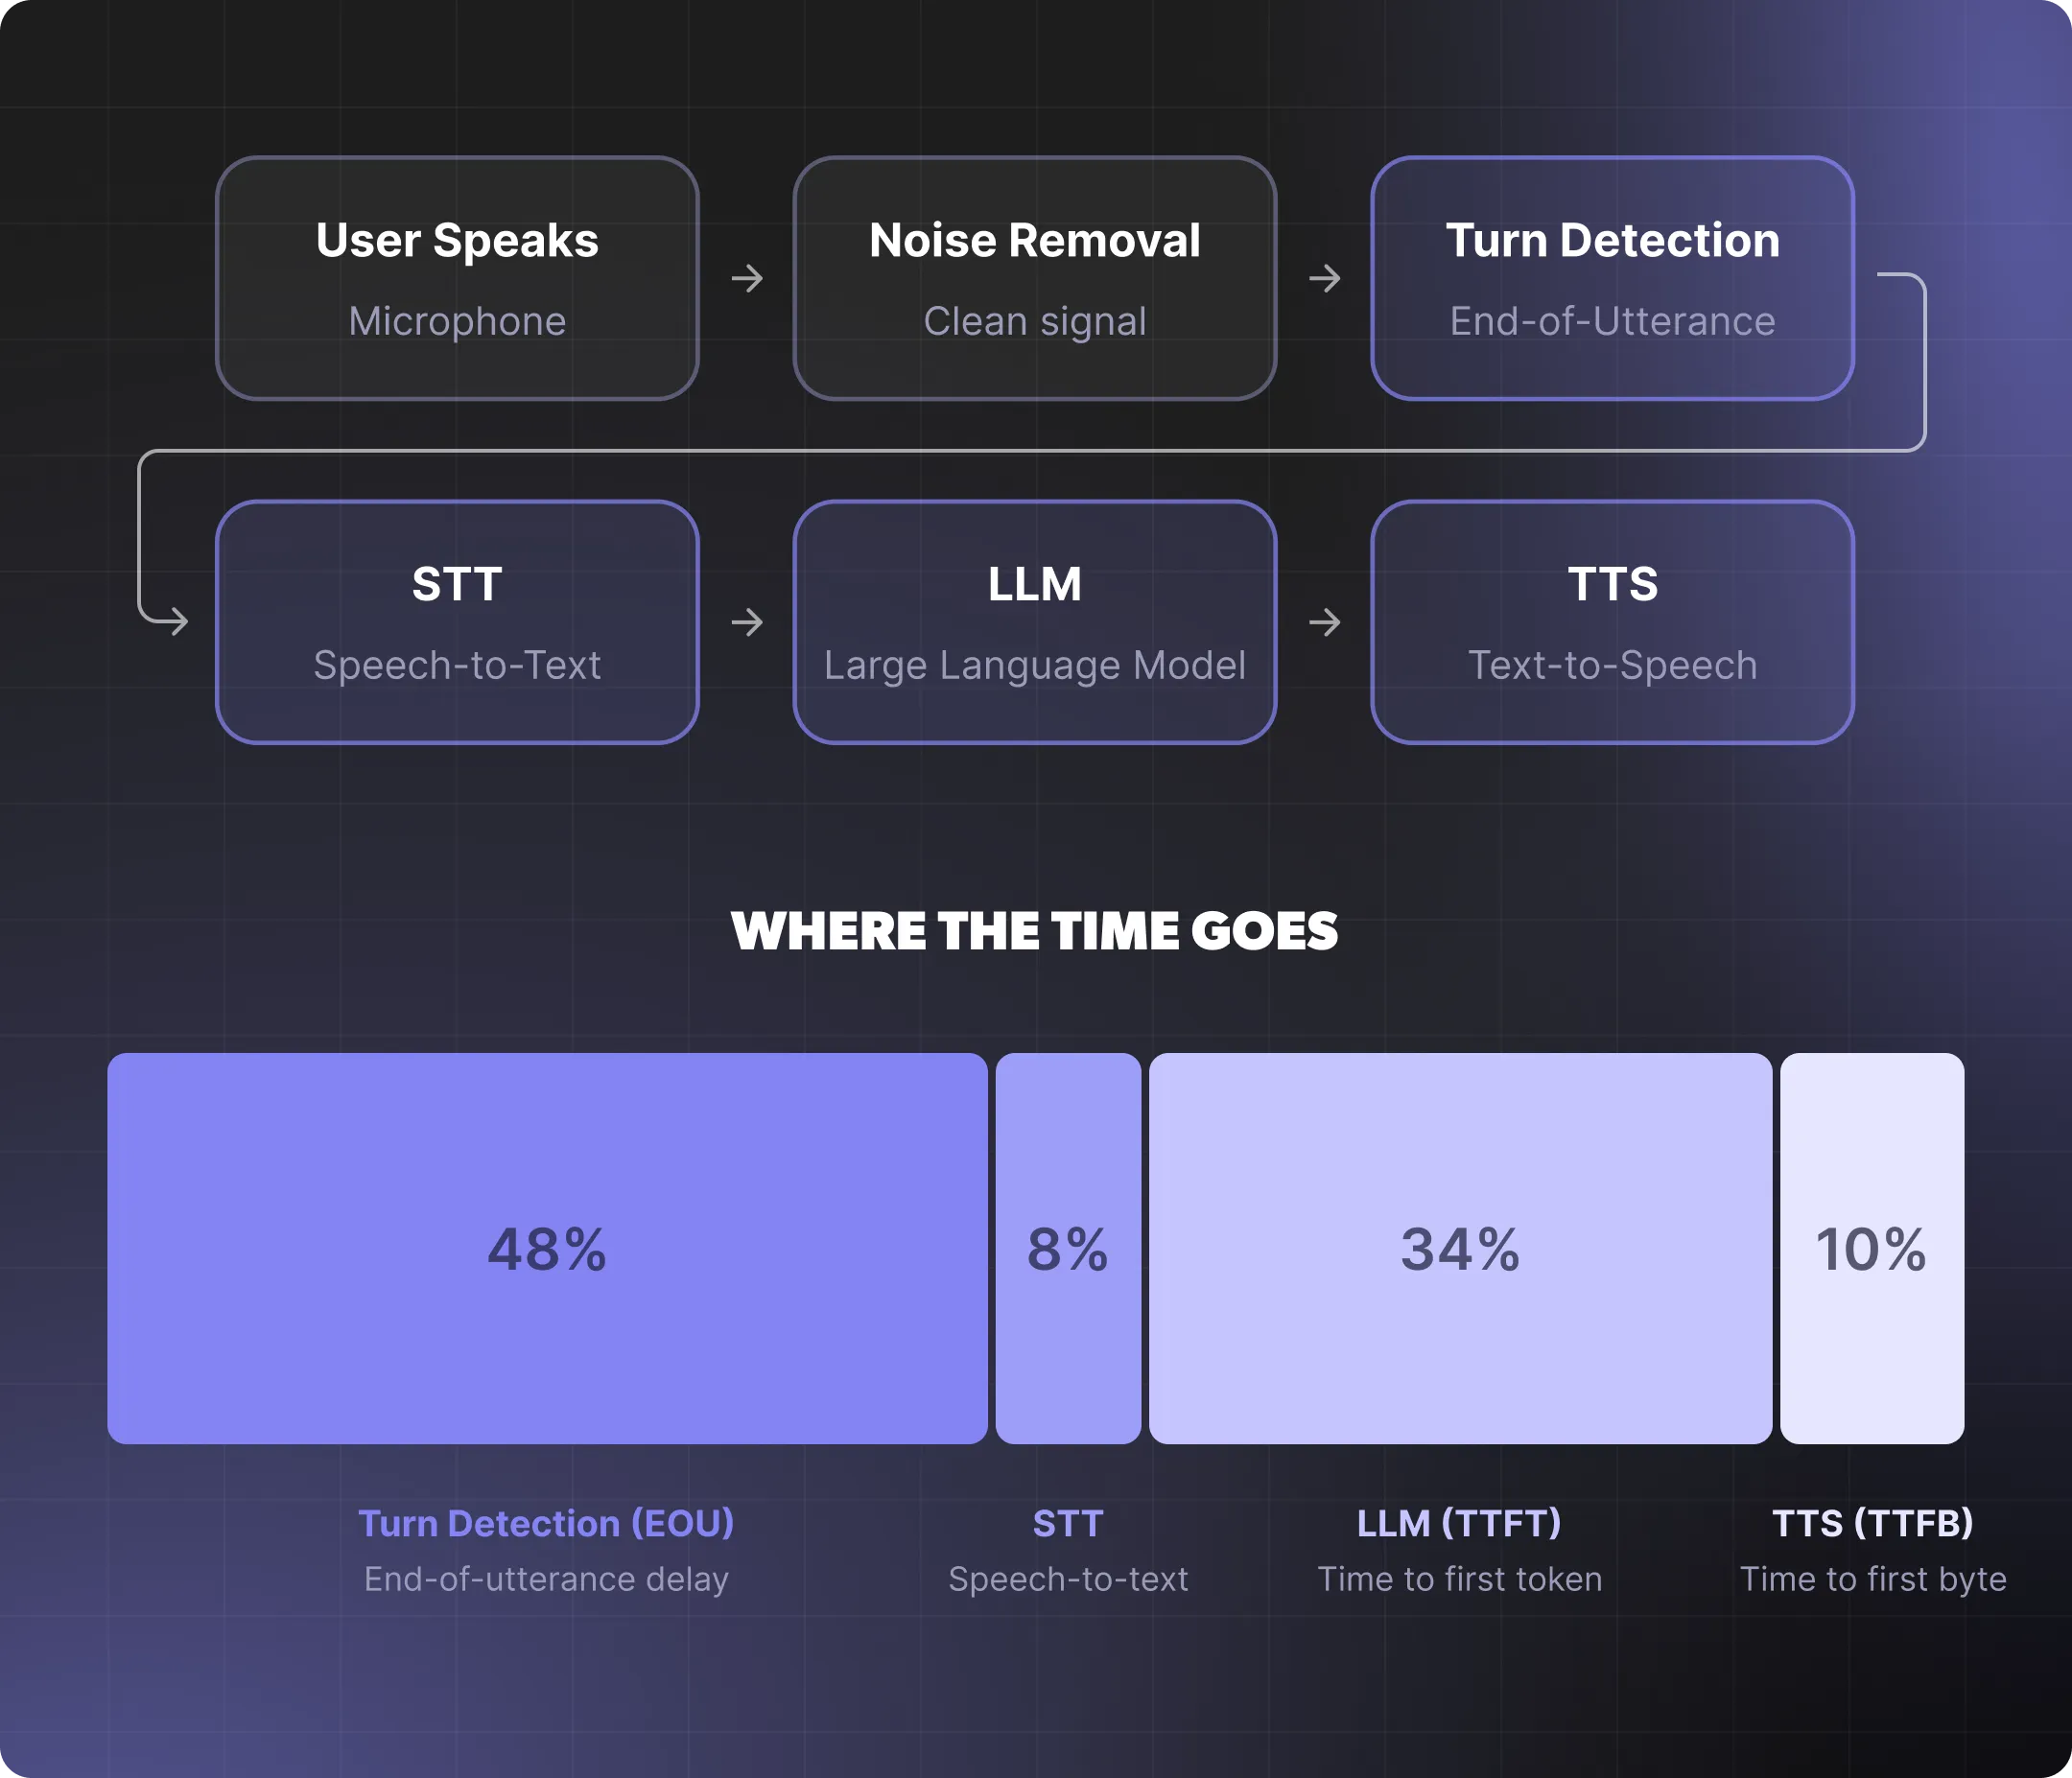
That processing is not free. The more tokens the model has to read before it can start generating, the longer your callers wait.

Prompt caching addresses this directly. The LLM caches its internal representation of the prompt so it doesn't have to re-read and re-process those tokens from scratch on subsequent turns. When the cache is loaded, the model skips straight to generating a response.

Within a single call, this is straightforward: after the first turn, the system prompt hasn't changed, so the cache stays valid and every subsequent turn benefits. The harder problem is caching across calls: keeping that saved work available when the next call comes in on the same agent.

The Structural Fix: Getting the Prefix Right

OpenAI's caching works on a prefix-match basis. When a request comes in, the model hashes the initial portion of the prompt and routes it to a machine that may already have that prefix cached. If the prefix matches, it picks up where it left off. If it doesn't, it starts from scratch.
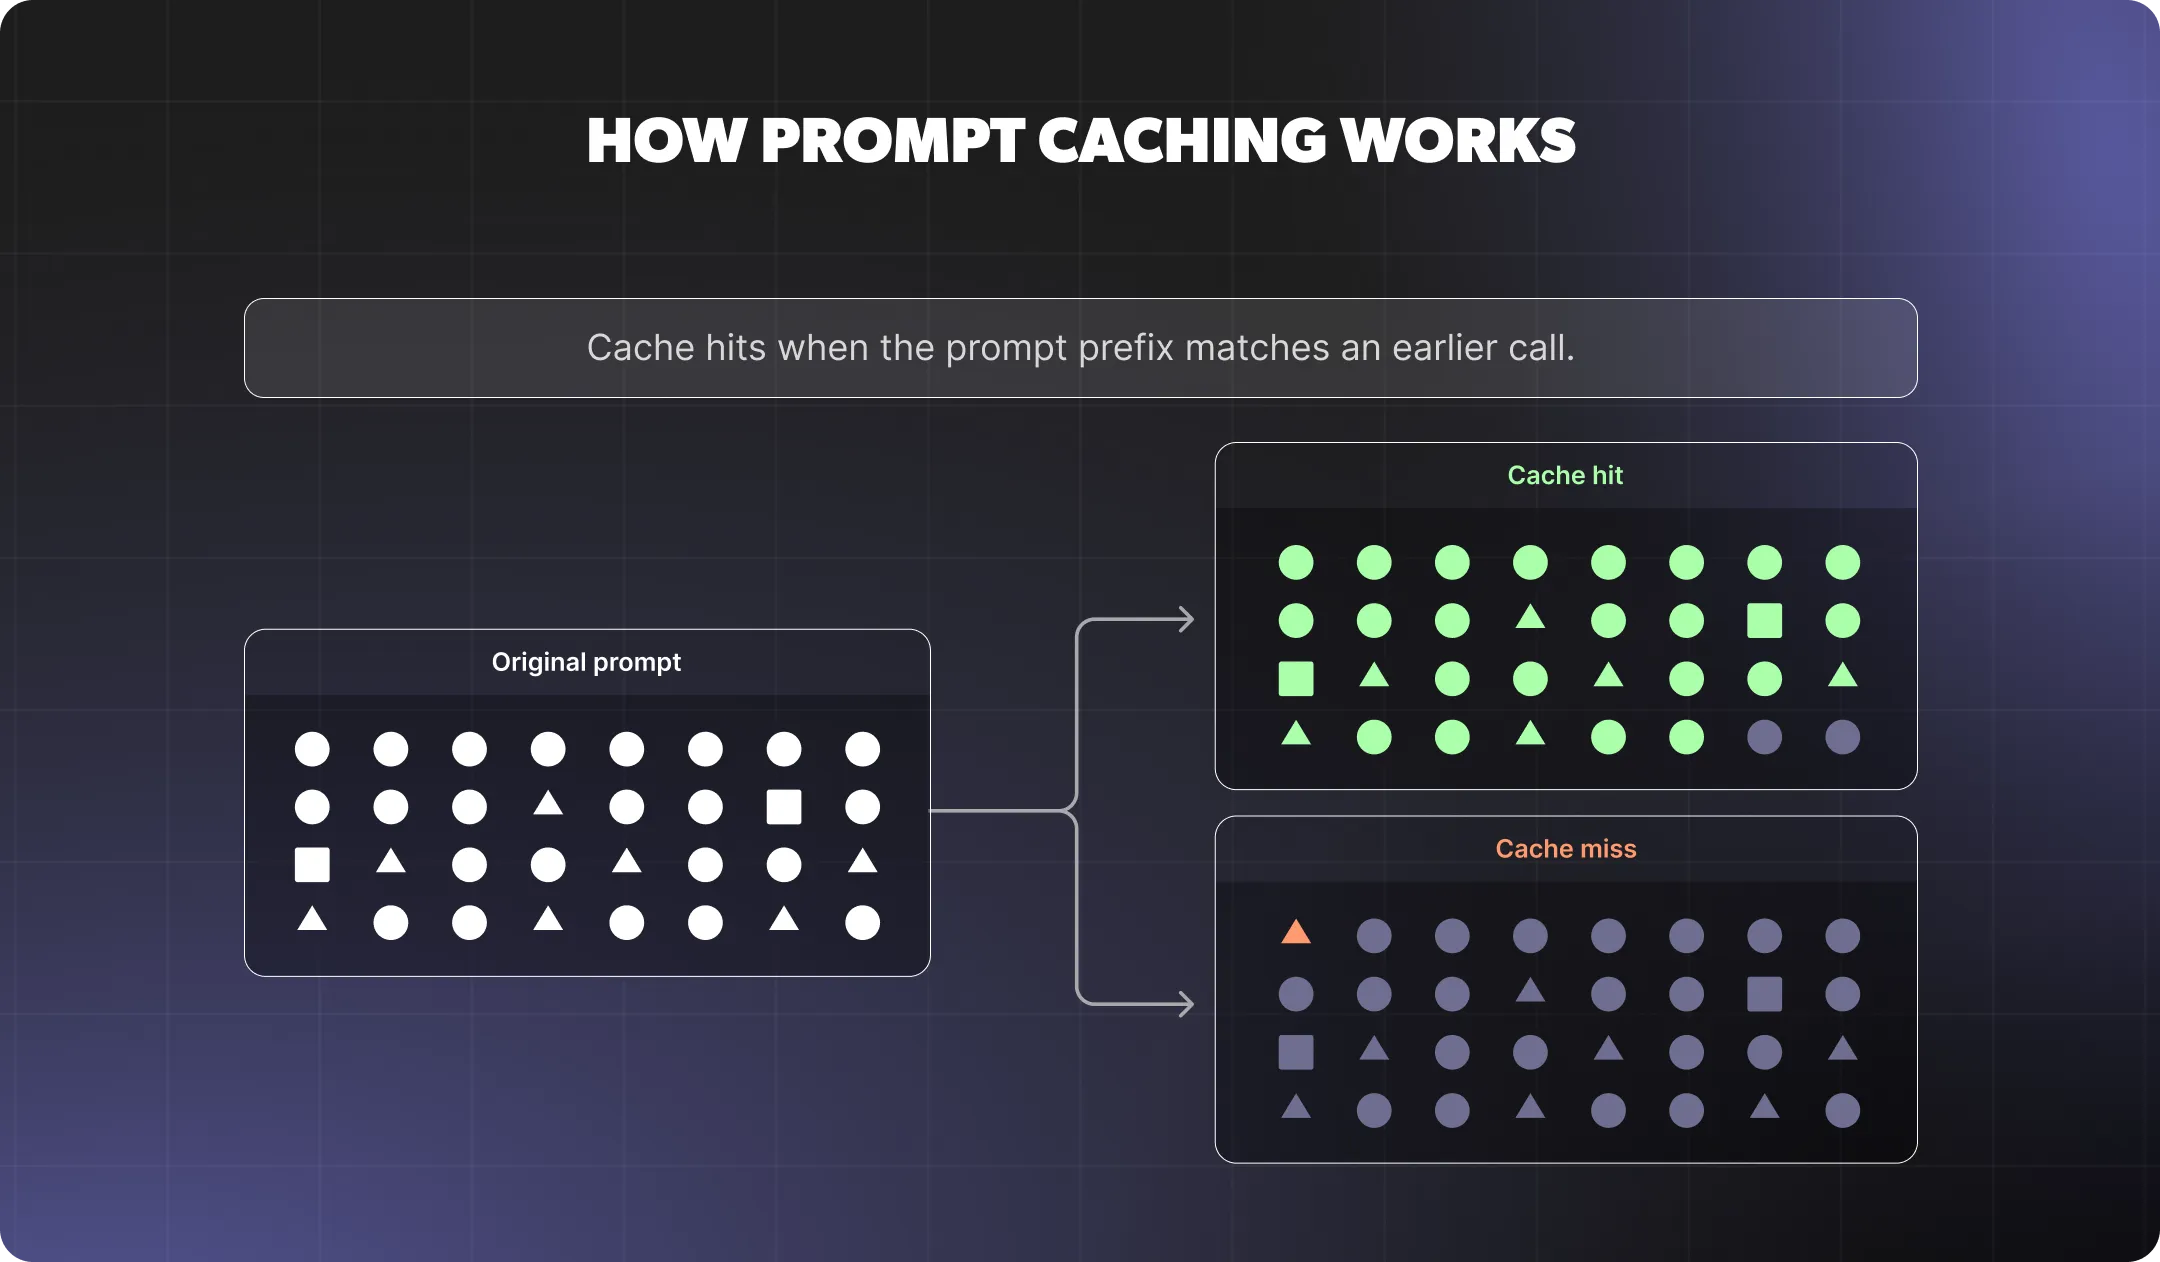
The implication: the stable part of your prompt needs to come first. The system instructions, tool definitions, response format: anything that doesn't change call to call should sit at the top of the prompt so the prefix is consistent and cacheable across every call to that agent.

We've been doing the work to ensure our architecture takes full advantage of this. The goal is to maximize the percentage of input tokens that are cached on any given turn. The more of the prompt the model can skip re-reading, the faster your TTFT.

The Configuration That Was Breaking Caching

Here's where things get counterintuitive.

Even when a prompt is well-structured, a single variable or character in the wrong place can invalidate the cache on every single call. If your system prompt starts with call-specific content like "You are calling [First Name], a [Lead Type] customer from [Salesforce field]," then every call looks different to the model. The prefix never matches, and the cache never hits. You're paying full processing cost every time.

This is exactly the pattern we found: call-specific details (first name, lead type, Salesforce attributes) were being rendered at the top of the prompt, invalidating the cache for new calls.
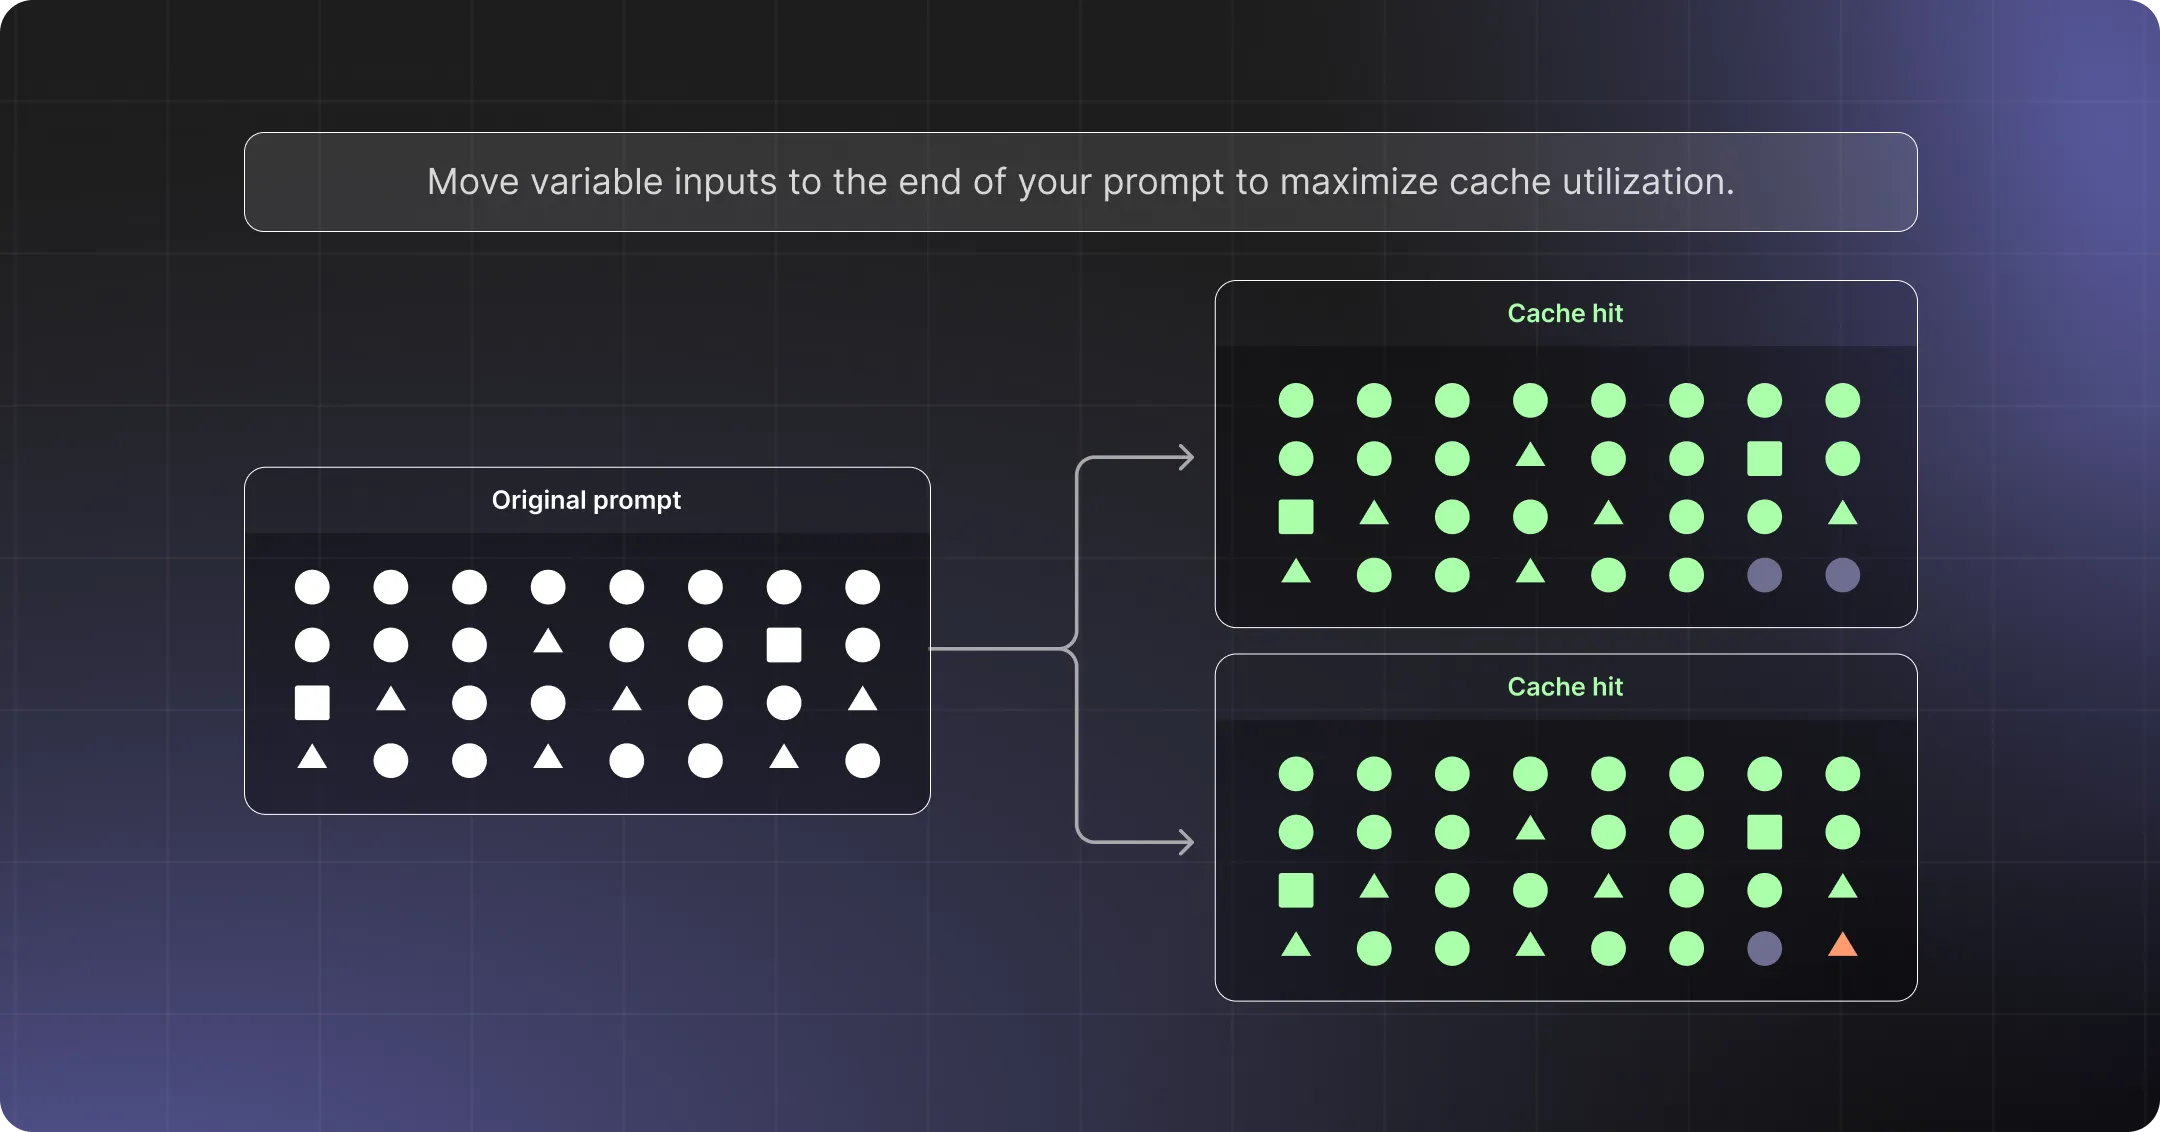
The fix was moving that dynamic content to the end of the context, after the stable system instructions. That way, the large, consistent portion of the prompt stays cacheable across calls, and only the small, variable portion needs fresh processing.

When the prompt is cacheable across calls, this creates a significant decrease to TTFT (time to first token), which in turn shortens the pause before an AI agent speaks. We found that this was a small structural change with a significant latency payoff.

What the Numbers Look Like

Before measuring improvement, we needed to understand where the opportunity was. The chart below breaks down the portion of cached requests by input size:
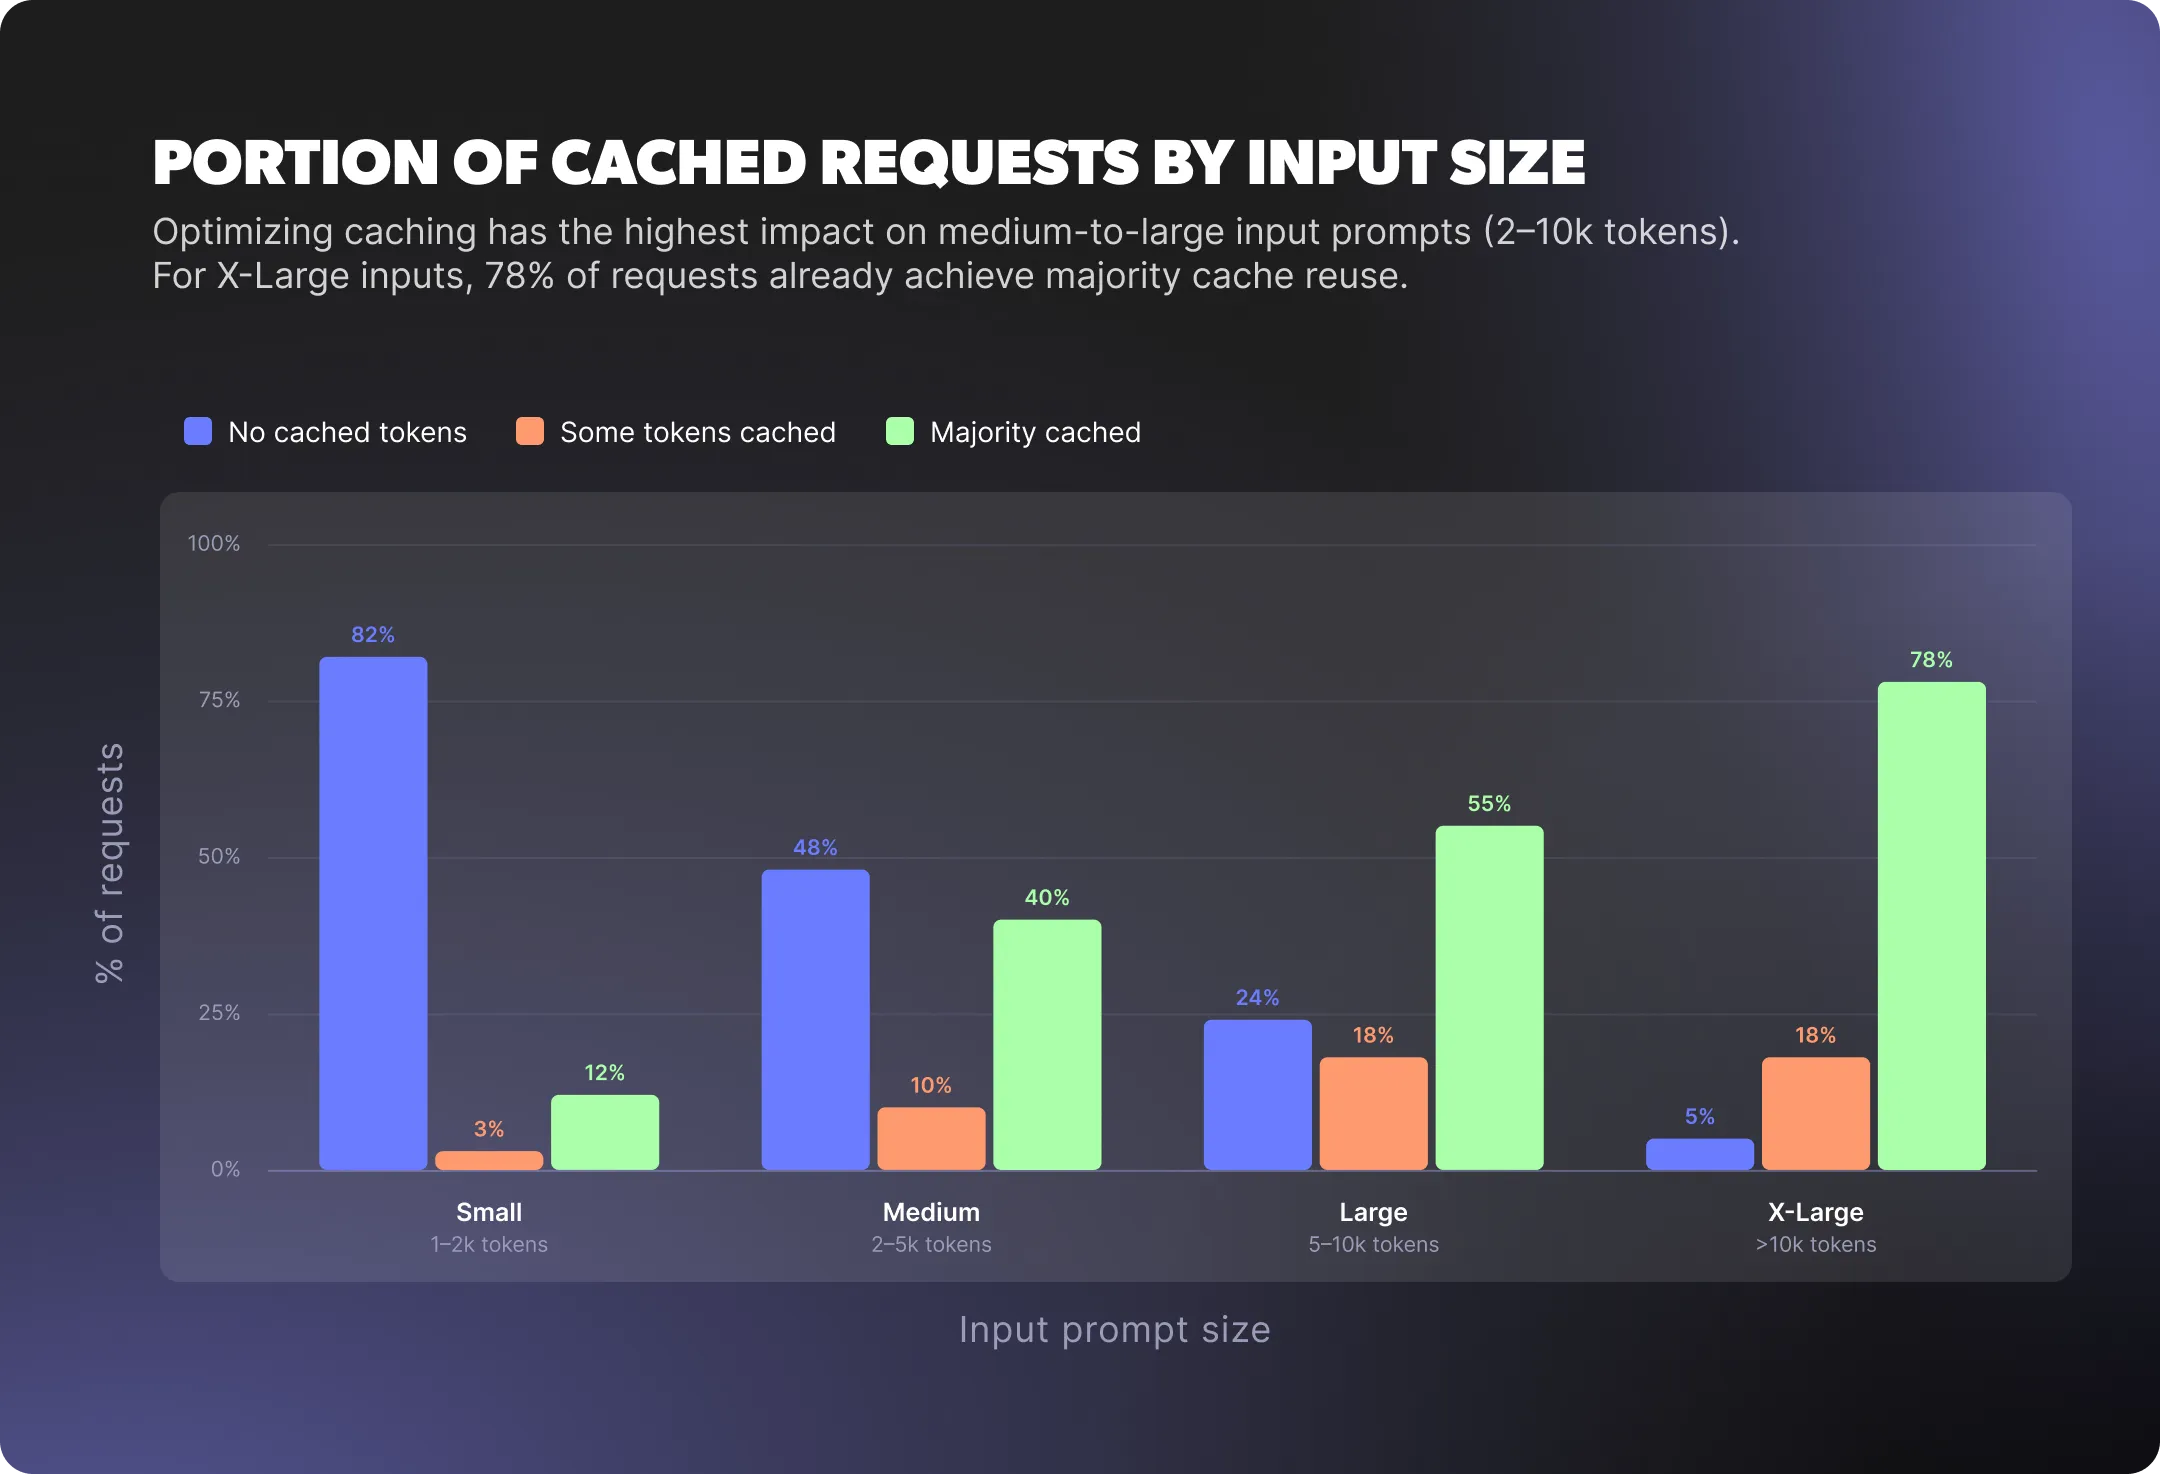
For extra-large inputs (over 10k tokens), 78.6% of requests already achieve high cache hit rates. The medium-to-large range (2k to 10k tokens) is where the highest volume of requests sits, and where fixing the prefix structure would have the broadest impact across the platform.

That's what we went after. The results show up clearly in cache hit rates on first turns. A first turn is the agent's opening response at the start of a new call. Unlike mid-call turns, which can reuse the cache built up within that conversation, a first turn has to rely on a cache carried over from a prior call. If that cache has expired, the model processes the full prompt from scratch. That's why first turns are the hardest to cache consistently, and the most important ones to get right.

  • Before April 1: Near zero. Almost every first turn was a cache miss.
  • Early April: Around 50% hit rate as the initial changes rolled out.
  • April 10 onward: Approximately 97% hit rate on first turns.
    ‍

That progression tracks directly with the E2E latency improvement: from the week of April 13 to early May, there was a 26% reduction in latency.

The work we're doing on latency doesn't stop here; we're still optimizing the percentage of tokens that are cached per request (not just whether any tokens are cached), which is the metric that drives the biggest TTFT gains. Our target is consistently above 90% of input tokens cached, given that the only thing changing turn-to-turn should be the new user utterance, a small fraction of the overall context.

What's Next

Prompt caching is one lever of improving latency, but it's not the only one.

We're actively testing faster voice models, smarter handling of tool calls so the agent says something natural while it looks up information rather than going silent, and additional model options with lower baseline latency. We're also exploring architectural changes that let us start LLM processing before the end-of-utterance detection fully completes, shaving off latency from both sides of the equation simultaneously.

Ready to see Regal's voice AI in action? Schedule a demo.

Frequently Asked Questions

What is time to first token (TTFT) in voice AI?

TTFT is the time between when a caller finishes speaking and when the language model begins generating a response. In a cascaded voice AI architecture that uses a separate LLM and TTS provider, TTFT is the primary driver of the pause callers hear before the AI agent speaks.

What is prompt caching and how does it reduce latency?

Prompt caching lets the LLM save its internal representation of your system prompt so it doesn't have to re-read and re-process those tokens on every turn. When a request comes in with a matching prompt prefix, the model skips the processing it already did and jumps straight to generating a response, reducing TTFT on every cached turn.

Why does contact-specific data in the system prompt hurt caching?

LLM caching works by matching the initial portion of a prompt (the prefix) against previously processed requests. If contact-specific details like a caller's name or Salesforce data appear early in the prompt, every call has a unique prefix, so no cached version ever matches. Moving that dynamic data to the end of the context preserves the cacheable prefix and allows caching to work across calls.

How much can prompt caching improve voice AI response times?

Results vary by architecture and prompt structure, but Regal has seen a 26% end-to-end latency drop by optimizing prompt structure for caching. The biggest gains come from maximizing the percentage of input tokens that are cached, not just whether any caching is occurring.

What else affects latency in AI voice agents beyond the LLM?

End-of-utterance (EOU) detection adds latency before the LLM request even fires. Text-to-speech (TTS) generation adds latency after the LLM responds. Tool calls (where the agent looks up information mid-conversation) can introduce silent pauses if not handled well. Reducing latency in production requires optimizing all of these components, not just model speed.

Treat your customers like royalty

Ready to see Regal in action?
Book a personalized demo.

Thank you! Click here if you are not redirected.
Oops! Something went wrong while submitting the form.
Repeated pattern of light purple angel wings with green star accents on a black transparent background.Repeated pattern of light purple angel wings with green star accents on a black transparent background.
Founded in 2020, Regal is an enterprise voice AI agent platform for contact centers. Regal helps businesses build, deploy, and manage autonomous AI agents across sales, support, and operations teams.

Latest Blog Posts

SEPTEMBER 2023 RELEASES

September 2023 Releases

Read More
SEPTEMBER 2023 RELEASES

September 2023 Releases

Read More
SEPTEMBER 2023 RELEASES

September 2023 Releases

Read More
How eHealth Elevated the Medicare Experience with Always-On Voice AI

eHealth’s AI agent streamlined Medicare enrollment and support by scaling up for peak call surges, eliminating after-hours wait times, and delivering exceptional experiences for beneficiaries.

Read More
Pinpoint Critical Knowledge Base Gaps with Regal Improve

‍Customer conversations are inherently dynamic, and Regal Improve’s Knowledge Base Coverage tracks changes in retrieval performance over time and at scale. This makes it easy to verify that KB updates increase coverage and if your documentation is keeping up with evolving customer requests.
Read More
November 2025 Releases

November's releases make it easier to scale your transfer-heavy call flows, with new tools that align dialer pacing to downstream agent capacity and streamline complex handoffs. You’ll also see improved post-call workflow accuracy, with reliable data extraction and disposition outcomes driven by LLM configurability and earlier validation.
Read More
Teaching Voice AI to Behave: Prompting Principles Every Parent Already Knows

Building a great AI voice agent isn’t so different from parenting a five-year-old: clarity, examples, and structure make all the difference. This post breaks down proven prompting principles—from positive framing and persona design to conversational guardrails—that help AI agents sound natural, stay on task, and follow directions every time.
Read More
Announcing Regal + ElevenLabs: Dynamic Voices for Every Conversation

Regal and ElevenLabs bring expressive, multilingual AI voices to customer and sales conversations, adapting tone and emotion in real time to boost conversions, trust, and satisfaction at scale.

Read More
Announcing Regal + Rime: Human-Like Voices at Enterprise Scale

Regal is partnering with Rime to deliver ultra-realistic, emotionally nuanced AI voices for enterprise contact centers. Discover new voice options that capture human qualities like pacing, resonance, and subtle expression, and learn how Rime’s technology powers conversations that build trust at scale.
Read More
Introducing Regal Improve: Conversation Insights for Smarter AI Agents

Regal Improve gives enterprises a scalable way to analyze thousands of AI agent calls, uncover conversation patterns, pinpoint knowledge gaps, and improve AI performance and customer outcomes over time.

Read More
Announcing Regal + Cartesia: Expanding Voice Options for Enterprise AI

Regal is partnering with Cartesia to deliver ultra-low latency, high-fidelity AI voices for enterprise contact centers. Explore new voice options, hear them in action, and learn about Cartesia's industry-leading voice AI offerings.

Read More
Introducing Knowledge Bases for AI Agents

Regal’s Knowledge Base feature brings Retrieval-Augmented Generation (RAG) to Voice AI Agents, enabling real-time access to proprietary data for smarter, compliant, and brand-aligned conversations at scale

Read More
April 2025 Releases

Here's our April 2025 product releases, including the early access period for our AI SMS Agents!

Read More
Debunking AI Agent Fears: "What if my agent says the wrong thing?"

Worried your AI Agent will say the wrong thing? Well, they might. But find out why that's just a natural part of the process, and how to mitigate the risk of it happening.

Read More
Introducing Regal IVR

Regal’s IVR leverages unified customer profiles to personalize inbound caller experience – delivering better customer experiences and business outcomes.

Read More
Introducing Progressive Dialer

Regal’s powerful progressive dialer multiplies your reach and maximizes agents’ time for personalized conversations.

Read More
March 2024 Releases

March 2024 Releases

Read More
Transforming the Patient Journey: From Reactive to Proactive Care

Regal helps Healthcare brands deliver proactive care, better patient outcomes, and improve provider efficiency by personalizing patient outreach and increasing patient engagement.

Read More
5 Essential SMS Campaigns for Home Services Companies

Use these 5 essential SMS campaigns for home services drive higher customer engagement and more revenue for your business.

Read More
Beyond CCaaS: How to turn your Contact Center into a Revenue Center

Why are so many contact centers stuck being cost centers? Why do they keep looking for cost reductions instead of revenue increases? Bad data and technology decisions are at the core of this issue. We need "marketing automation" (aka unified customer profiles, event-driven systems and a/b testing) like Regal.io in the contact center to empower teams to start looking for incremental revenue instead.

Read More
February 2024 Releases

February 2024 Releases

Read More
6 Use Cases for REGAL AI Call Summaries

Discover 6 ways customers are using REGAL AI Call Summaries to drive better business outcomes.

Read More
The Next Step Forward in AI will come from Consumer Businesses

Consumer businesses are implementing AI-enabled customer experiences without any change in behavior on the part of consumers, which is leading AI to become common with more speed than past transitions like the internet and the smartphone. And it means that the next step in AI will not come from the LLM providers. The next big step forward in AI rests in the hands of consumer businesses.

Read More
Beyond CCaaS: From Customer Data Dips to Customer Data-Driven

Modernizing your Contact Center to drive personalization and more revenue requires a new tech stack you won't get with legacy CCaaS.

Read More
Innovating on Patient Care | B2C Sales Podcast Episode 7

Explore Eric Hauser's remarkable career journey from GovTech to healthcare disruption at Cadence, highlighting the transformative power of innovation, collaboration, with a special focus on the pivotal role of Regal in driving patient engagement and outcomes.

Read More
The Future of Conversation AI | B2C Sales Podcast Episode 6

Discover the transformative power of AI in conversations and how Regal's cutting-edge technology is reshaping call analysis and optimization for enhanced customer experiences with Balto's Marc Bernstein on our B2C Sales Podcast.

Read More
How SoFi, Perry Health & Allstate Personalize CX at Scale

Discover how Regal.io's AI-powered personalized outreach solutions are revolutionizing outbound sales and customer experience across industries like healthcare, finance, and insurance in our latest eBook, "Modernizing Outbound Contact Centers: How to Treat Millions of Customers like One in a Million."

Read More
January 2024 Releases

January 2024 Releases

Read More
Introducing Custom Tasks: Sometimes Actions Speak Louder Than Words

Use custom tasks to orchestrate Agent actions beyond just customer conversations.

Read More
2023 Year In Review

We look back at major product releases in 2023.

Read More
November 2023 Releases

November 2023 Releases

Read More
Introducing Collaboration-Native Features to CCaaS

Combining collaboration functionality into CCaaS workflow tools invites more cross-functional users from a company to participate in designing the end-customer experience, leading to better omni-channel orchestration and customer outcomes. Learn more about Regal's collaboration features.

Read More
Introducing QA Scorecards: Uplevel Agent Performance

Uplevel agent performance with Regal's QA Scorecards. With QA Scorecards, managers can ensure that all interactions meet the criteria and standards of excellence established by your company.

Read More
October 2023 Releases

October 2023 Releases

Read More
How Regal.io is Turning the $40B CX Industry on Its Head

Jon Heaps, former VP, Channel at Observe.ai, Talkdesk, and inContact interviews Alex Levin, Co-Founder & CEO of Regal.io, about the history of the contact center industry and some of the key challenges teams making outbound calls face as customers demand more online experiences.

Read More
New SMS & Branded Caller ID Rules Are Enhancing Customer Experience

Are you using Branded Caller ID for outbound calls or SMS? New SMS and Branded Caller ID regulations rolled out in Q2 2023 that you MUST KNOW ABOUT. The new regulations require that every company register their SMS campaigns and Branded Caller ID campaigns before being allowed to send texts or brand calls.

Read More
August 2023 Releases

August 2023 Releases

Read More
4 Essential SMS Campaigns for Life Insurance Companies

The fastest growing insurance brands are using SMS campaigns in intelligent ways to drive higher customer engagement and more revenue. You can too with these 4 essential SMS campaigns.

Read More
Need to Boost Call Center Productivity? Switch to a Power Dialer

Discover how a power dialer can revolutionize outbound calling and enhance sales team productivity. Schedule a consultation with our experts to explore Regal.io's power dialer.

Read More
The Financial Impact of Working with Regal.io: 547% ROI

Discover how working with Regal.io led to a 547% ROI for businesses. Learn more about the financial impact and success stories in our comprehensive case study.

Read More
Announcement: Regal 1:1 Email Channel

Regal's powerful 1:1 email channel enables agents to have more touch points with customers from a unified platform.

Read More
Announcement: Regal Conversation Intelligence

Regal’s Conversation Intelligence drives higher conversion rates for B2C sales teams. We use both the traditional QA/coaching tools, and brand new conversational triggers that allow you to update customer profiles and send automated follow up messages based on what is said in a conversation.

Read More
Announcement: Regal SMS Suite

Regal’s SMS Suite allows brands to actually drive revenue from SMS. Drive cross-channel engagement using our comprehensive Triggered & Scheduled SMS Journeys (aka SMS Marketing), 1:1 SMS Conversations (aka 2-Way SMS), and AI SMS Bot.

Read More
Announcement: Regal Segment Builder

Regal’s powerful, no-code Segment Builder enables any business user to segment, target, suppress, and send blasts of cross-channel communications (SMS, calls or webhooks) to their customers – all based on a real-time unified customer profile.

Read More
Announcement: Regal Unified Customer Profile

Regal's Unified Customer Profile gives you a complete view of each customer including 1st party data, 3rd party data and conversation intelligence so you can deliver cross-channel orchestration in conversational channels like phone and sms.

Read More
July 2023 Releases

July 2023 Feature Releases

Read More
Friends don’t let friends buy CCaaS

Learn when event-driven sales systems like Regal will disrupt the $40B Contact Center Software and CCaaS industry, by improving customer experience and increasing revenue.

Read More
June 2023 Releases

June 2023 Feature Releases

Read More
Caller ID vs. CNAM vs. Branded Caller ID: What’s the Difference?

Caller ID, CNAM, and Branded Caller ID all help identify an incoming call and, therefore, increase call answer rates. Find out how they differ and how outbound phone sales teams can utilize each to reach prospects and customers effectively.

Read More
May 2023 Releases

May 2023 Feature Releases

Read More
How Regal Helps Consumer Lenders Achieve Growth in Tough Times

Our Co-Founder & CTO, Rebecca Greene, spoke with journalist Tony Zerucha at the recent Fintech Nexus USA 2023 event about how consumer lenders are using personalized phone and SMS sales outreach to obtain growth despite high inflation and rising interest rates.

Read More
Outbound Call Center: What It Is, How It Works & Best Practices

The fastest growing High Consideration brands have invested heavily in outbound call centers for sales and marketing. With the right technology, staffing and measurement, you too can build a high performing outbound call center to help hit your growth goals.

Read More
April 2023 Releases

April 2023 Feature Releases

Read More
Regal is a Winner on G2!

We’re excited to announce that Regal.io has been awarded 6 awards in G2’s Spring 2023 Reports. 

Read More
March 2023 Releases

March 2023 Feature Releases

Read More
Meet Regal Call Branding™: Branded Caller ID for 400M+ US Devices

We are excited to announce Regal Call Branding™ including Branded Caller ID. Available on all 400M wireless devices in the US (as well as most of Canada and the UK), Regal Call Branding™ puts you in control of what people see when you call their cell phone – including showing your brand and/or logo.

Read More
February 2023 Releases

February 2023 Feature Releases

Read More
January 2023 Releases

January 2023 Feature Releases

Read More
Outbound Campaign Compliance 101: TSR, TCPA, DNC, EBR, and ATDS

Ensure proper consent before contacting consumers via call or text. Ignoring regulations like TCPA and TSR poses risks. Stay compliant to safeguard your operations and reputation.

Read More
Q&A with Perry Health’s Scott Chesrown

Get behind-the-scenes insights about Perry Health’s 23% revenue increase with Regal.io. Perry Health’s Scott Chesrown sat down with Regal.io and discussed how they implemented outbound sales technology, integrated new capabilities into their process, and built on their early success.

Read More
Regal's 2022 Year In Review

Dive into Regal's 2022 Year In Review and catch up on the highlights from our most powerful releases throughout the year.

Read More
Drive More Contact Center Revenue With These 6 Holiday Tips

It’s the holiday season and you’d like to hit your December revenue goals. Outbound B2C sales during the holidays can be a major performance driver – if you're prepared and you have the right tools in place. Use these seven tips to get your outbound B2C sales in shape for holiday success.
Read More
Regal.io Raises $38.5M in Series A Funding

Today we are excited to announce that based on the success our customers are seeing using Regal.io, we have raised $38.5 million in Series A funding led by Emergence Capital to continue to invest in our teams and products.

Read More
Announcing our Integration with mParticle

Our integration with mParticle enables you to create a unified customer profile and connect other first party customer data.

Read More
What is a Journey Builder?: A Complete Guide

Say goodbye to batch processing, complicated SQL queries or custom engineering to decide who to call. Journey builders help B2C create more timely, relevant and personalized outreach to customers.

Read More
Why Outbound Calls Get Marked as SPAM or SPAM LIKELY & How to Fix It

Legitimate B2C brands are incorrectly being flagged as spam by cell carriers. If your current call patterns are causing your legitimate calls to be flagged, there is a new process to remove spam flags.

Read More
August 2022 Releases

August 2022 Feature Releases

Read More
Goodbye Regal Voice, Hello Regal.io

Friends and supporters, We are excited to announce our updated branding and website. It better captures what we stand for.

Read More
November 2022 Releases

November 2022 Feature Releases

Read More
Announcing our Integration with Twilio Segment

We are excited to announce our integration with Twilio Segment, allowing you to seamlessly connect your first-party customer data with Regal.io and 200+ other integrated tools.

Read More
October 2022 Releases

October 2022 Feature Releases

Read More
Milestone: $1 Billion Revenue Driven for Our Customers

We are thrilled to announce that Regal.io has driven over 20M conversations between our customers and their end users, leading to $1 billion in revenue driven to date.

Read More
September 2022 Releases

September 2022 Feature Releases

Read More
The Rise of Voice AI Agents: Real-World Deployments Across the Enterprise

In this AI4 fireside chat, Regal.ai COO Sahil Mehta and TaskUs CCO Jarrod Johnson explore how enterprise organizations are deploying voice AI agents across customer experience, support, and sales. They share real-world deployments, discuss quality and ROI trade-offs, and outline best practices for aligning operations and product teams when adopting AI agents at scale.
Read More
How We Built a Voicemail Detection Model that Outperforms the Industry

Our engineering team breaks down how we improved our Voicemail Detection model by aligning the taxonomy with the actual audio, scaling labels, and choosing representations before adding model complexity.

Read More
Staying Compliant with the New TCPA Rules: A Guide for Enterprise Contact Centers

New TCPA updates require interpreting opt-out intent and suppressing outreach across all channels. See how you can use Regal's AI Decision Node to stay compliant.

Read More
Best LLMs for Voice AI Agents in October 2026: Voice CX Benchmark Results

We ran the latest models from DeepSeek, Anthropic, Google and OpenAI through the Voice CX Benchmark. Here's which ones we're prioritizing for voice AI agents, and which ones we're passing on.

Read More
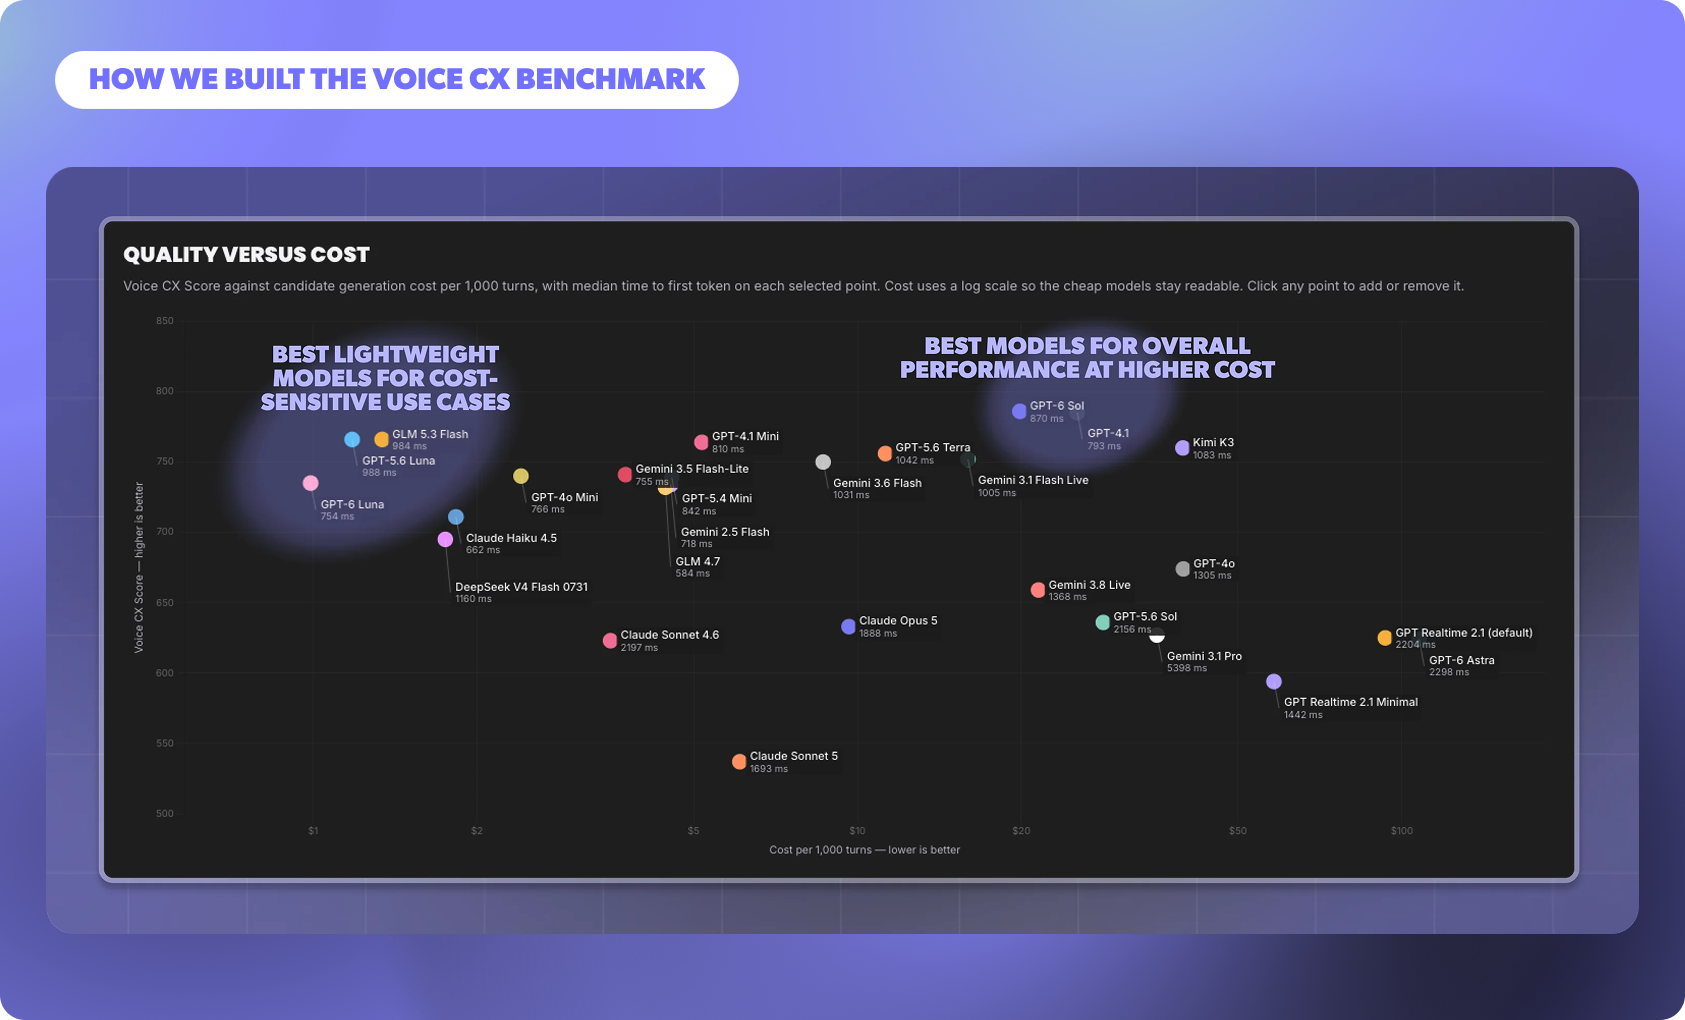
October 2026 Product Recap

Last month, we shipped releases that improve your contact center operations by extracting business insights with Copilot and reducing wasted agent minutes with our new Voicemail Detection model. The result is more reliable, productive AI agents that can drive revenue for your business.
Read More
From Assistant to Expert: Review, Orchestrate, and Extract Insights with Copilot

Copilot started as the place you asked questions. Over the last few months it has become the place where agents are improved, tested, and monitored.

Read More
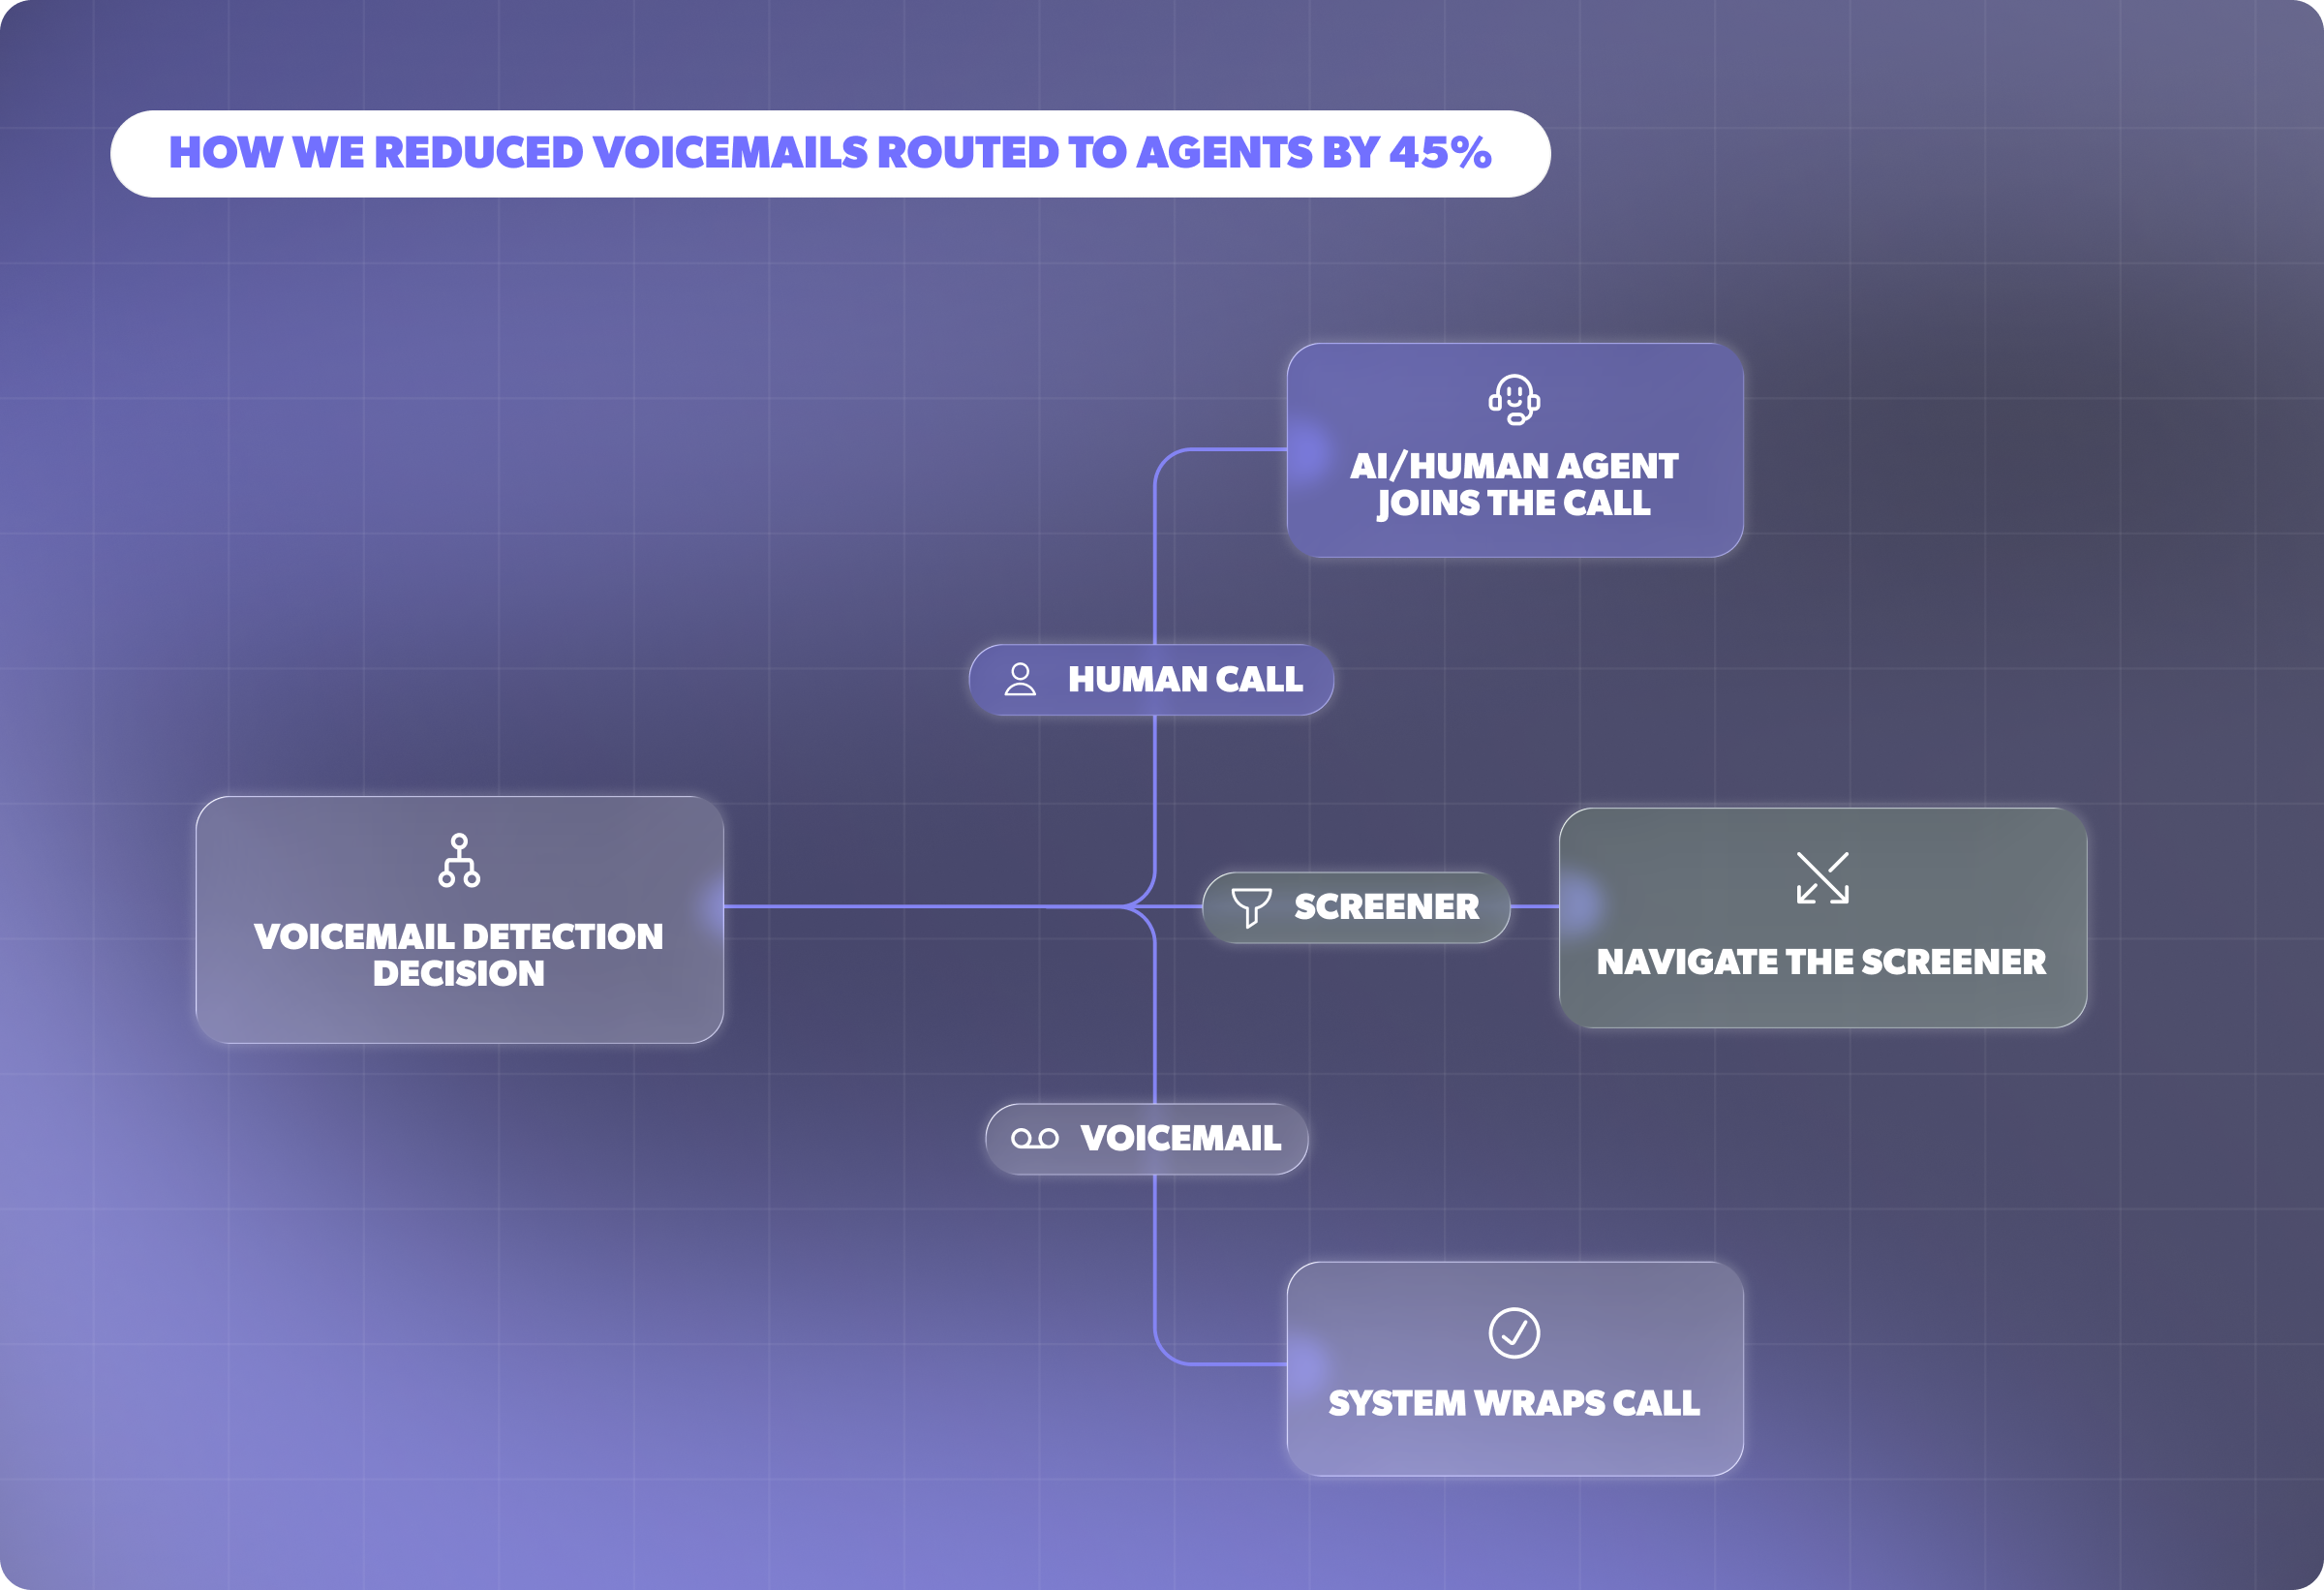
How We Built the Voice CX Benchmark

Enterprises need voice agents that hold a natural, human-like conversation while moving each call toward its goal and staying within compliance boundaries. The Voice CX Benchmark scores models on exactly that: how well they progress the call turn by turn, how safely and clearly they communicate, and how quickly they respond.
Read More
How Sentiment Scoring Works in Regal

Every qualifying voice call that runs through Regal gets two sentiment scores: one for the agent, one for the contact. Here's what actually produces those numbers.

Read More
AI Agent Templates: More Industries, More Detailed Prompts, and Custom Actions

Building a voice AI agent from scratch means writing prompts, wiring up actions, and defining guardrails before you can even test a call. Our upgraded agent templates skip that setup.

Read More
Introducing Regal’s Voicemail Detection Model: How We Reduced Voicemails Routed to Agents by 45%

With Regal’s next-generation Voicemail Detection model, you can now classify voicemail, iOS or Google call screeners as separate categories with very high accuracy. This enables screener-specific handling, ultimately reducing missed agent connections.

Read More
September 2026 Product Recap

Last month, we shipped releases that make it easier to build, monitor, and test agents in one interface. Copilot Canvas brings building, editing, and testing into one interface and it can work straight from your files. Multi-state sticky notes let your team document decisions directly on a live agent.
Read More
Give Copilot More Context With File Uploads

Copilot now lets your team upload files, like spreadsheets, scripts, and flowcharts, directly as inputs. This gives Copilot the context it needs from the start, making it easier to extend Copilot into new agent use cases as they come up.

Read More
How Regal AI Agents Navigate Complex IVRs

How Regal AI Agents recognize, navigate, and continuously improve at getting through third-party IVR phone trees, from classification and the Press Digit action to node isolation and real-world test simulations.

Read More
August 2026 Product Recap

Last month, we launched features that extend your management of AI agents via MCP and CCaaS platforms. Debug based on agent versions or simulation runs, and manage AI analysis data points via Copilot and Regal MCP. As a Five9 AI Agent Connect partner, Regal now has a dedicated integration API built for Voice AI agents.
Read More
Build, Test, and Monitor Agents on One Interface with Copilot Canvas

Copilot Canvas brings agent building, testing, and monitoring into one interface, so you can edit, test, and track performance without leaving Copilot chat.

Read More
Why We Signed the Open Weights Letter

We've always been careful to never give frontier labs the right to keep or train on customer data. With open weight models, we can go further: when a customer invests in improving these models, that value accrues to them, not to a lab.

Read More
July 2026 Product Recap

Last month, we shipped updates that make AI agents sound more responsive and easier to run at scale. Dynamic Voices lets your agent adjust its pace the second a contact asks for it, and Copilot now handles IVR and disposition management.

Read More
GPT-Live and the Rise of the Full-Duplex Voice Agent

OpenAI launched GPT-Live, a new generation of voice models, and described it as a “full-duplex” model. We tested GPT-Live directly to see how the theory holds up in practice.

Read More
Real-Time Observability Across Every AI Agent

The Regal Observability Dashboard gives your team real-time visibility into AI agent performance — tracking hallucination rates, guardrail breaches, latency spikes, and more across every call, automatically.

Read More
Extend what your team can build, see, and improve with Regal MCP

Regal MCP connects your Regal platform to AI environments like Claude, Cursor, and ChatGPT. Your team can pull transcripts, inspect configurations, and trigger actions without switching context.

Read More
May 2026 Releases

This month, we shipped Regal MCP, which extends what your team can build, see, and improve. Regal MCP opens the platform to your external AI environment, so team members can take Regal actions directly from tools like Claude without switching context.

Read More
Dialing Compliance: How We Scaled Outbound Calling Reliably

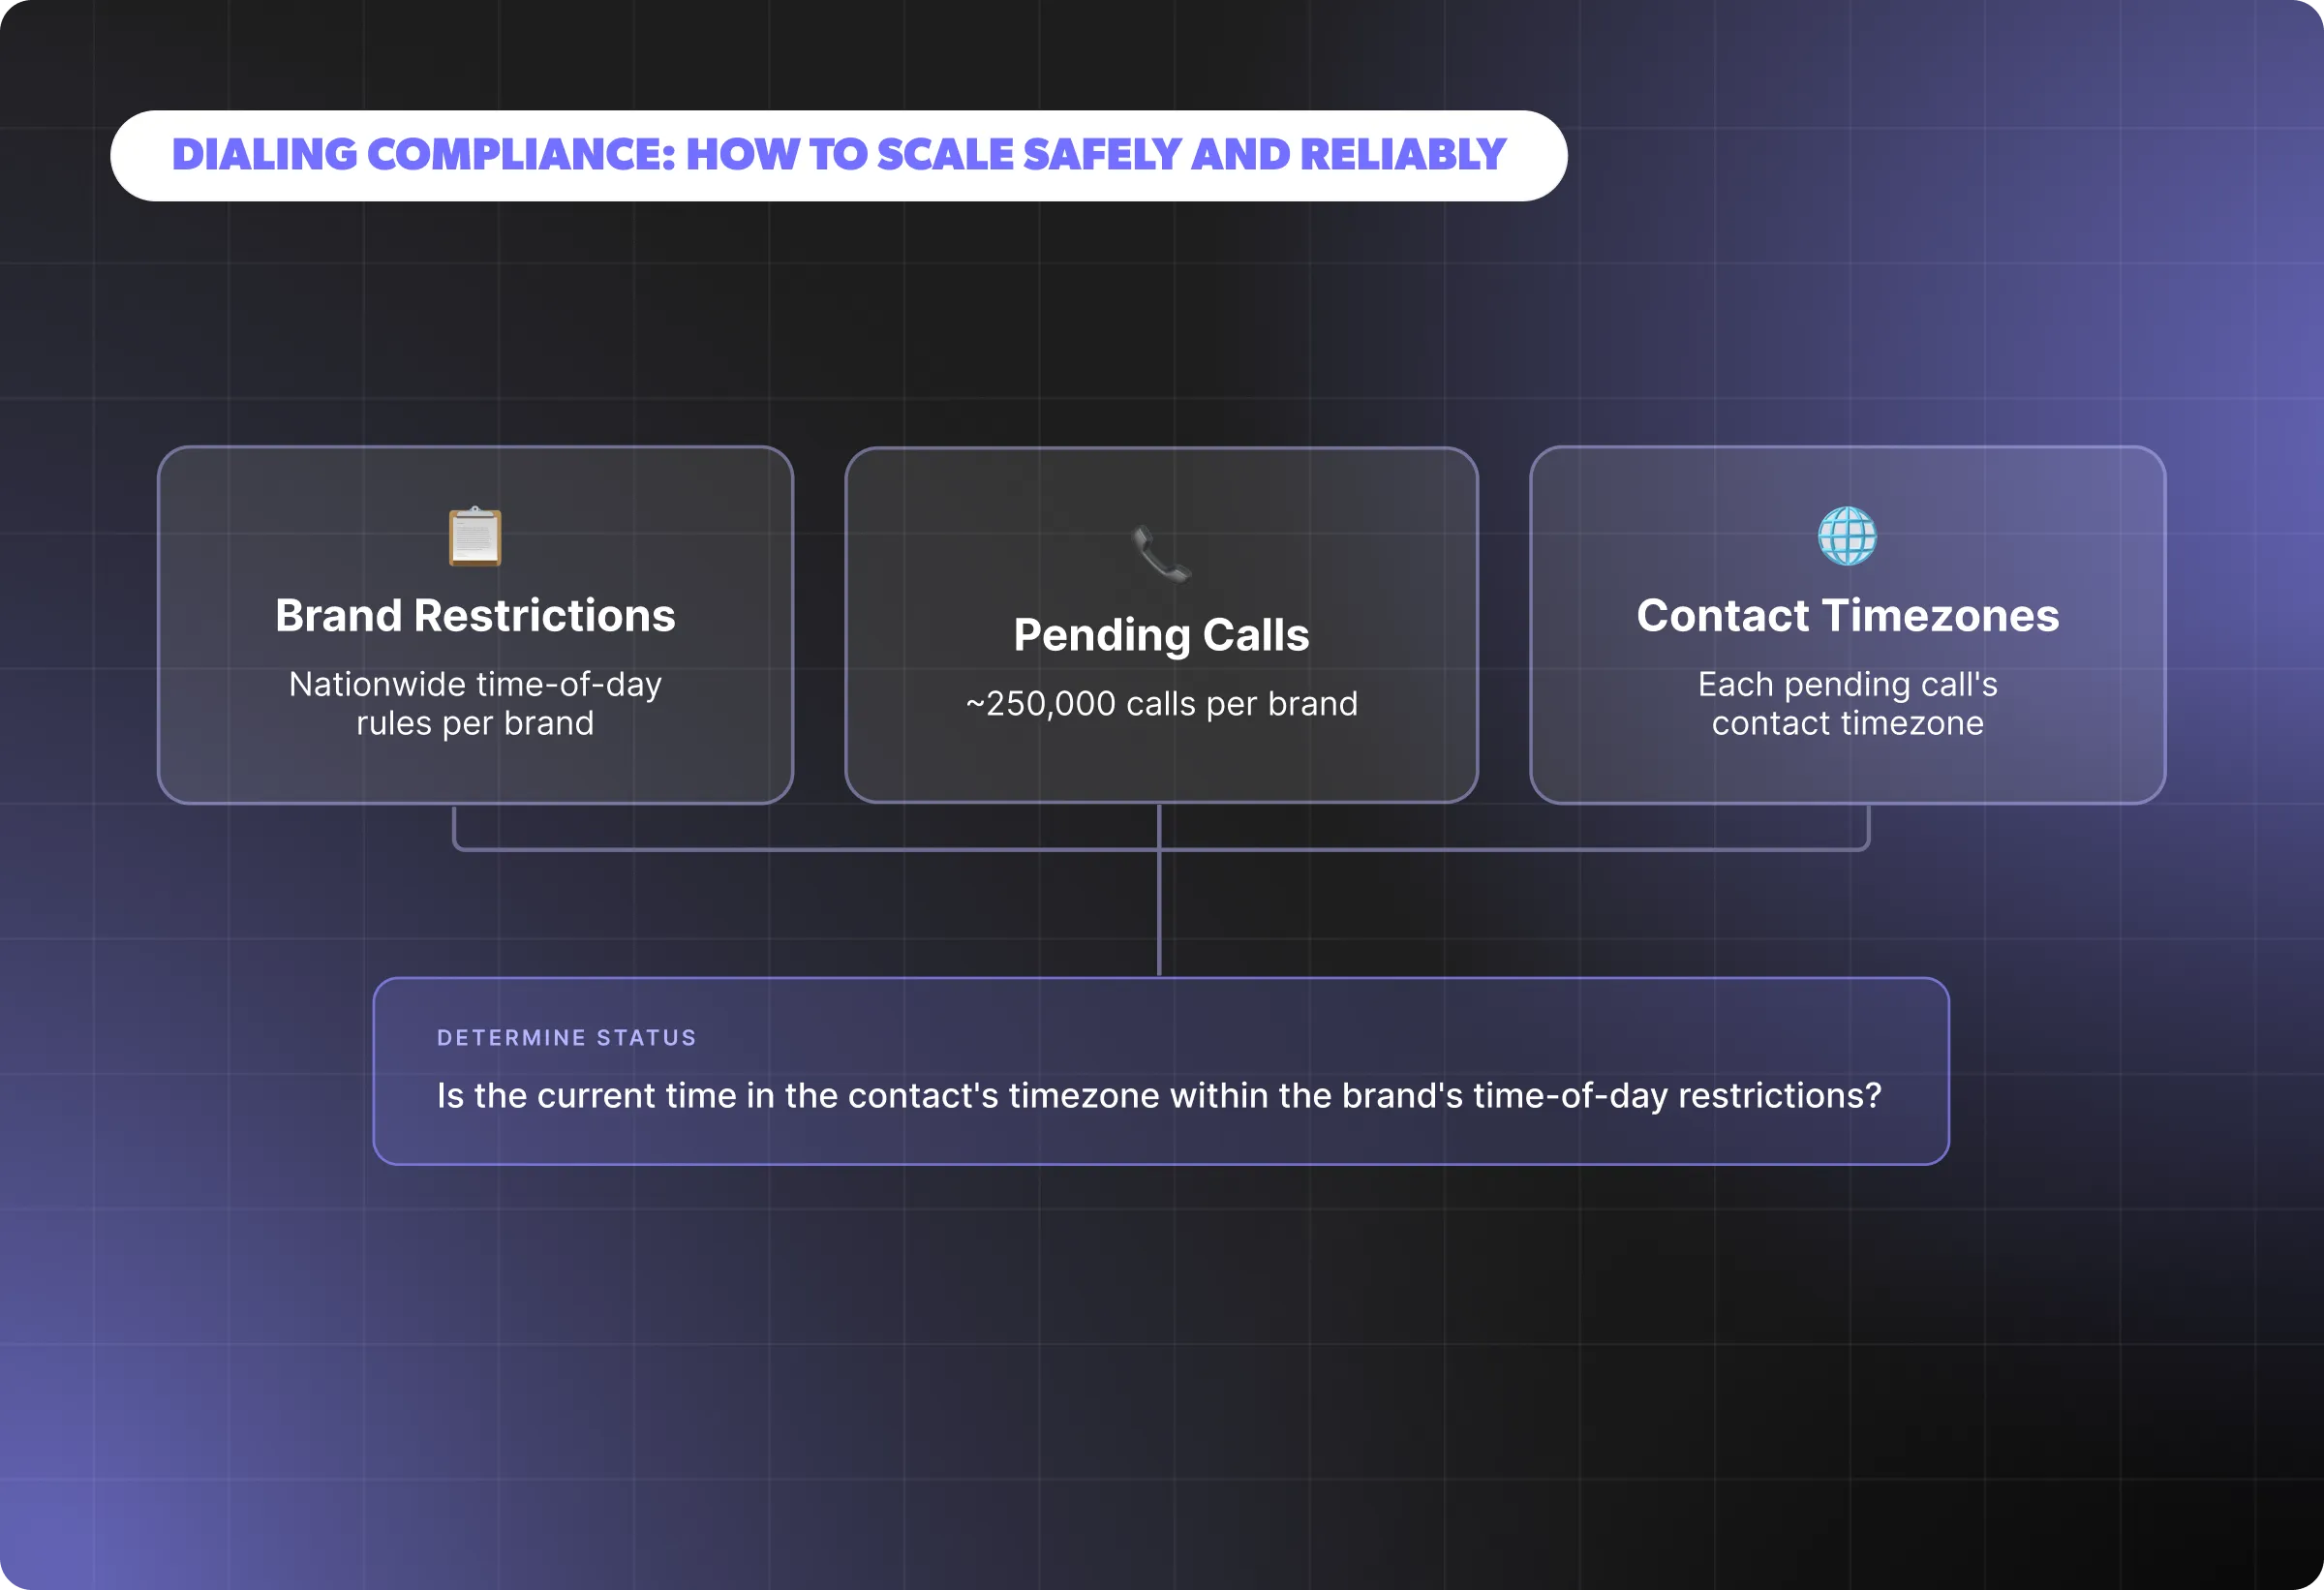
Behind a fragmented and ever-changing regulatory landscape is a simple goal: protecting people from unwanted or poorly timed outreach and giving them control over how they’re contacted. In practice, that responsibility translates into a set of checks that must be validated.

Read More
We Just Hit 500M Calls. Here's What We Learned.

This number is a milestone that represents a fundamental shift in customer experience and how businesses grow. Curious what this number really looks like? We put it into perspective.

Read More
How Gemini 3.5 Flash performs for Voice AI agents

Every new LLM comes with trade-offs between latency, cost, and quality — and Regal tests all of them against real voice AI agents. Here's what we found when we ran Gemini 3.5 Flash through our benchmark.

Read More
April 2026 Releases

This month, we shipped enhancements that help you quickly make proactive fixes and customize AI agents to your brand. Copilot does more troubleshooting work on your behalf and with headless WebRTC, you can embed Regal voice agents inside your own product UI.

Read More
From Kickoff to First Live Call: What a Real Voice AI Deployment Looks Like

After powering over 400 million calls, we've found that the contact centers that win with voice AI aren't just the ones that deploy first. They're the ones that learn fastest.

Read More
No Need to "Press 1": How AI Phone Agents Go Beyond Automation

AI phone agents aren't just better phone trees. They are autonomous systems that can understand caller intent, retrieve relevant information from your CRM in real time, execute actions, handle objections and clarifications, and complete the conversation without human involvement.
Read More
Why Your AI Voice Agent Sounds Robotic And How to Measure for Improvement

Voice AI is architectural, not cosmetic. Warm words on a broken flow make things worse. But warm words on a well-structured, well-measured system compound over time.

Read More
The PII Question Every Regulated Industry Asks Before Deploying AI Agents

When prospects in healthcare and financial services hear "PII," they often imagine bulk data transfer: the idea that deploying an AI agent means copying a database somewhere. In most modern deployments, that's not what's happening.
Read More
Why Customers Confide in Voice AI Agents More Than Your Reps

At HumanX 2026, Regal's VP of Growth Lex Sivakumar shared what 400 million analyzed calls reveal about voice AI. Customers are not just accepting well-built AI voice agents. They are opening up to them more than they do to humans.

Read More